Toy Model of Activation Obfuscation

I completed this work as part of the BlueDot Impact Technical AI Safety Project. I’d like to thank the BlueDot Rapid Grant Program for funding this work.
Training against probes is considered a forbidden technique, because the model might learn to obfuscate its activations instead of behaving better. Can we create a toy example of this? More specifically – 1 under optimization pressure, will a toy model learn to encode a feature to be challenging to detect with linear probes?
In this research, I give theoretical and empirical evidence that models can and will defeat adversarially-trained linear probes, at least in some configurations. This project demonstrates the risks of training against linear probes, as a way to align models. Training against linear probes should thus be done with extreme caution or not at all, unless the failure mode I demonstrate can be mitigated.
I investigated this problem with a simple residual-stream MLP architecture: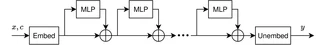
The model tries to learn $y = \text{sat}(x, -c, c)$ (the saturation function, equivalently $y = \max(-c, \min(c, x))$). $x$ is a vector of dense features sampled uniformly from $[-3, 3]$, and $c$ is a scalar sampled uniformly in $[1, 2]$. This is a fairly easy function to learn – it takes just $2 \cdot \text{len}(x)$ neurons to learn exactly if you use ReLUs. 2 The harder question is, can a model do this without storing $c$ in the residual stream, in a way that can be linearly probed? Here:
- $c$ represents some safety-relevant behaviour we want to probe for – say, deception.
- $x$ represent various other features that a model might want to represent, uncorrelated with $c$.
- $y$ represents some sort of computation the model would like to make, dependent on $c$.
- For example, based on how deceptive the model intends to be (represented at some earlier layer), the model might upweight misleading information at some later layer.
- Such an action will ultimately come down to various computational primitives.
- $\text{sat}$ is hopefully representative of such a primitive – for example, it can be considered a rough approximation to the more common sigmoid function. (Note: $\text{sat}$ was primarily chosen for its theoretical properties, as discussed below, not because it’s necessarily a natural computational primitive.)
Why this task, and why this model?
The toy architecture is at least vaguely similar to the transformer architecture. It’s missing attention (and the entire notion of a token sequence) and LayerNorm. However, it doesn’t really add anything new to a transformer, so any obfuscation that this model learns could plausibly also be learned by a transformer.
The learned function is not linearly separable in $c$. Thus, once the model has finished computing $y_i$ for one feature $x_i$, it can just leave $y_i$ in the residual stream. This is vaguely analogous to how probe accuracy gets worse on the last layers of a transformer model, as the model starts shifting its representation from more abstract concepts to the exact text it wants to output.
Because it takes at least $2 \cdot \text{len}(x)$ neurons to implement $y$ exactly with ReLUs, the model can’t erase $c$ until it’s encountered that many neurons. If we keep the MLP width below that threshold, we can be sure the model has represented $c$ somehow in the first layer (assuming the model learned the task fully). Narrowing the MLP width further ensures $c$ is represented in later layers as well. We can use this property in experiments to guarantee that the model is representing $c$ at a particular early layer.
Two implementation notes:
- My empirical experiments use GeLUs rather than ReLUs, so the exact neuron-count bound doesn’t strictly transfer, but the qualitative argument – that some minimum number of neurons is needed to compute $y$ – should still hold.
- For training and theoretical simplicity, this work fixes the embedding and unembedding matrices to be rectangular identity matrices (i.e. ones on the main diagonal, zero elsewhere).
Related work
- Neural Chameleons find that you can fine-tune models to evade latent space linear probes, including for previously unseen probes
- However, as far as I can tell, they use fixed probes, which don’t rule out the model simply learning to apply a fixed translation or rotation to its representation. This is obfuscation in some sense, but not particularly complex obfuscation.
- Training Against Harmfulness Probes Induces Harmlessness without Refusals train adaptive probes on harmfulness, where the probe is updated regularly along with model training, and find that this successfully improves harmlessness.
- They do this on a real model. Plausibly, the task that their model learns can be accomplished with equally high scores without needing to be harmful. In contrast, since I use a toy model, it’s easy to construct an environment where the model has to hide its activations to succeed.
Results
I present my results in three parts:
- Part 1: Analytic nonlinear feature obfuscation with two MLP blocks
- An analytic construction using a small number of neurons, that fully defeats Difference-of-Means probes (by having the mean activations be a constant in $c$) and effectively defeats logistic regression probes, as long as consecutive probed layers are at least 2 MLP blocks apart.
- Part 2: Initial empirical results
- The setup and results for a single training run. I find evidence that the trained model has successfully learned to reversibly obfuscate its activations from a linear probe at a single layer, while still successfully learning the task.
- Part 3: Sweeping hyperparameters
- A preliminary exploration of sweeping some hyperparameters, to see how robust the model’s training is to different conditions. Generally, it’s possible to reproduce the results for larger models and different configurations, although further effort is needed in tuning the training process.
Future work
There’s a lot of potential extensions to this work.
- Most obviously – can this behaviour be reproduced at LLM scale?
- How hard is it for a model to hide from a nonlinear probe? Or from probes at multiple or all layers? Can we study how likely “obfuscation at layer N” is to generalize to obfuscation at other layers or more complex obfuscation?
- Are there different obfuscation strategies that occur when attention is introduced?
- The model was forced to obfuscate its activations by the experiment setup. What happens if we give it an “out” – i.e. it can solve the task in some harder way?
- This might better mirror how real-world environments are (ideally) set up: ensuring that there is a genuine acceptable solution, rather than the reward-hacking solution being the only success path.
- If you spent more effort on tuning the training process for different model sizes and configurations, can you develop useful scaling laws or predictions for larger models?
Code
The full research repository is available on GitHub.
Footnotes
